
Image
A prompt originally used for Nano Banana Pro (and adapted here for Seedream 4.5) to generate an image of a woman with dramatically exaggerated, surrealistically long legs, using a low-angle perspective to emphasize height.
Browse 32,996 free prompts for Nano Banana 2.1, Seedance 2.5, GPT Image 2.5, ChatGPT, Claude, Gemini and coding assistants, with sample outputs. Copy one, fill in the blanks, or run it in your favourite AI.
A prompt originally used for Nano Banana Pro (and adapted here for Seedream 4.5) to generate an image of a woman with dramatically exaggerated, surrealistically long legs, using a low-angle perspective to emphasize height.

A prompt originally used for Nano Banana Pro (and adapted here for Seedream 4.5) to generate an image of a woman with dramatically exaggerated, surrealistically long legs, using a low-angle perspective to emphasize height.
Full body shot of a woman with dramatically exaggeratedly long legs (surreal proportion, unnaturally elongated). **Camera:** Full body shot, low angle perspective to emphasize height/length, sharp focus, cinematic light.

A simplified Chinese prompt for the Seedream 4.5 model (Doubao) that achieves superior Korean aesthetic portrait results compared to the complex Nano Banana Pro prompts. The user outlines the simplification process (removing JSON, redundancy, and using abstract terms) and provides the resulting concise prompt, which focuses on specific facial features, makeup, accessories, and composition for a 'sweet and cool' Korean girl group look.
4宫格拼图,3:4比例,2×2排列;近景特写,平视近拍,人物占比大,冷白干净背景。参考图严格同一人、零偏差;精致脸、大眼、右眼下小痣、细鼻梁;冷粉白皙,轻柔焦但保留细节,面中高光,鼻尖脸颊微红,少量雀斑。韩系清透淡妆,粉腮红扫到鼻梁,水润渐变唇。黑色中分长直发+少量碎发;左右粉色发夹金属可见。手靠近脸唇突出细节:超长浅色闪片立体美甲+多枚粉色糖果花朵戒指。白毛绒外搭+浅粉吊带露肩;甜酷软糯。四格动作:托脸冷淡微委屈;触唇平静略撩;桌沿侧看放空;抵下巴克制微笑。高亮柔光、低对比、阴影浅;冷白主调粉色点缀;背景弱虚化少纹理;写实韩杂女团质感,轻玻璃光泽。
You are an expert cybersecurity certification instructor and exam-question analyst.
2

3
GOAL
4
Analyze the multiple-choice cybersecurity question provided below and teach me how to identify the correct answer. Produce a structured, exam-focused explanation that is accurate, practical, and easy to remember.
5

6
CONTEXT
7
I am preparing for a cybersecurity architecture certification examination. I need more than the correct answer. I want to understand:
8
1. The principle being tested
9
2. Why the correct option is the best answer
10
3. Why every other option is incorrect
11
4. How to recognize similar questions in the examination
12
5. The relevant framework, control, standard, or architectural concept
13

14
SOURCE REQUIREMENTS
15
Use the question, answer options, supplied explanations, and references as the primary sources.
16

17
When external verification is available:
18
- Verify technical claims using authoritative primary sources
19
- Prioritize official publications such as NIST, ISO, CIS, government publications, and vendor documentation
20
- Do not invent control numbers, quotations, requirements, distances, or regulatory rules
21
- Clearly distinguish requirements stated by a source from your own interpretation
22
- If the supplied answer appears inconsistent with an authoritative source, state the discrepancy instead of automatically accepting it
23
- Include direct links to the most relevant official sources
24
- Do not rely on unverified blogs when an official source is available
25

26
INSTRUCTIONS
27
Follow this exact response structure:
28

29
1. Correct Answer
30
Start with:
31
“✅ Correct Answer: complete_answer_option”
32

33
2. Concept Being Tested
34
Explain the main security, risk, architecture, or governance principle in plain English.
35
State what the examiner is trying to test.
36
Identify the decisive words or phrases in the question.
37

38
3. Short Reasoning
39
Give a concise explanation of why the correct answer is best.
40
Limit this section to one or two short paragraphs.
41

42
4. Option-by-Option Breakdown
43
Analyze every option in the same order in which it appears.
44

45
For each incorrect option, use:
46
“❌ option_text”
47
- Plain-English rationale
48
- Why it is relevant but not decisive, if applicable
49
- Why it does not answer this specific question
50
- Exam hook
51
- Elimination tip
52
- Memory tip
53

54
For the correct option, use:
55
“✅ option_text”
56
- Plain-English rationale
57
- Why it directly satisfies the question
58
- A practical example
59
- Exam hook
60
- Relevant control or framework mapping
61
- Memory tip
62

63
5. Key Exam Distinction
64
Compare the two or more concepts that candidates are most likely to confuse.
65
Use a simple format such as:
66
- Concept A = what it measures or decides
67
- Concept B = what it measures or decides
68

69
6. Framework or Control Mapping
70
Identify the applicable framework, publication, control family, or architectural principle.
71
Explain the connection without overstating what the source says.
72
Include publication section or control identifiers only when verified.
73

74
7. Practical Scenario
75
Give one brief real-world example showing how the correct principle would affect an architecture or risk decision.
76

77
8. Master Exam Hack
78
Provide:
79
- One reusable decision rule
80
- One elimination strategy
81
- One common trap to avoid
82

83
9. One-Line Memory Trick
84
Give one short and memorable sentence.
85

86
10. Final Answer
87
End with:
88
“Final answer: ✅ complete_answer_option”
89

90
STYLE AND QUALITY RULES
91
- Write in clear, professional, plain English
92
- Use informative headings and bullet points
93
- Be detailed but avoid unnecessary repetition
94
- Keep each option explanation proportionate
95
- Preserve important technical distinctions
96
- Do not use raw HTML
97
- Do not merely restate the supplied explanation
98
- Do not assume that the marked answer is correct without checking the reasoning
99
- Do not introduce facts unsupported by the question or reliable sources
100
- If the question is ambiguous, explain the ambiguity and identify the best exam answer
101
- If a fixed number or universal rule does not exist, say so clearly
102
- Use emojis only for correct answers, incorrect answers, exam tips, and memory aids
103
- Keep the complete response suitable for revision notes
104

105
QUESTION TO ANALYZE
106
paste_the_complete_question_here
107

108
ANSWER OPTIONS
109
A. option_a
110
B. option_b
111
C. option_c
112
D. option_d
113

114
SUPPLIED ANSWER, IF AVAILABLE
115
[Paste the marked answer here, or write “Not provided”]
116

117
SUPPLIED EXPLANATIONS AND REFERENCES
118
[Paste any explanations and source links here, or write “None provided”]
SOURCE VALIDATION MODE
2
Before answering, validate the marked answer against the cited official sources. Prefer the latest applicable official edition, but note when the question is based on a specific older edition. Cite the exact publication and relevant control or section when it can be verified. Never claim that a source uses exact wording unless that wording appears in the source.

A simplified Chinese prompt for the Seedream 4.5 model (Doubao) that achieves superior Korean aesthetic portrait results compared to the complex Nano Banana Pro prompts. The user outlines the simplification process (removing JSON, redundancy, and using abstract terms) and provides the resulting concise prompt, which focuses on specific facial features, makeup, accessories, and composition for a 'sweet and cool' Korean girl group look.

A comparison between images generated by Seedream 4.5 and Nano Banana 2 using the same prompt, noting that Seedream's aesthetic aligns better with Asian female beauty standards, while Nano Banana's result is good but 'too honest'. The prompt describes a young Asian beauty in specific attire and setting.
生成图片:{argument name="人物描述" default="年轻亚裔美女,冷白皮美女,黑色长卷发"},穿{argument name="服装" default="白色吊带+酒红杂色开衫+酒红长裤"},站在{argument name="场景" default="室内简约场景(桌面摆红酒+手机),背景墙简约挂画"},{argument name="光线和氛围" default="夜景,室内暗光,中景构图,慵懒随性的日常穿搭氛围,画面细节真实自然"}。
A comparison between images generated by Seedream 4.5 and Nano Banana 2 using the same prompt, noting that Seedream's aesthetic aligns better with Asian female beauty standards, while Nano Banana's result is good but 'too honest'. The prompt describes a young Asian beauty in specific attire and setting.
**Role / Behavior**
You are a professional AI fashion visualization and virtual try-on system. Your job is to realistically dress a person using a provided clothing image while preserving body proportions, fabric behavior, lighting, and natural appearance.

---

**Inputs (Placeholders)**

* `` → Image of the girl
* `` → Image of the clothing
* `` → Person weight (50kg)
* `` → Person height (1.57m)
* `` → Desired background (outdoor)
* `` → Image quality preference (realistic)

---

**Instructions**

1. Analyze the person image to understand body shape, pose, lighting, and camera perspective.
2. Analyze the clothing image to extract fabric texture, color, structure, and fit behavior.
3. Virtually fit the clothing onto the person while preserving:

   * Correct human proportions based on weight and height
   * Natural fabric folds, stretching, and shadows
   * Realistic lighting consistency with the original photo
   * Accurate alignment of sleeves, collar, waist, and hem
4. Generate **three realistic try-on images** showing:

   * **Front view**
   * **Side view**
   * **Back view**
5. Ensure the face, hair, skin tone, and identity remain unchanged.
6. Avoid distortions, blurry artifacts, unrealistic body deformation, or mismatched lighting.

---

**Output Format**

Return exactly:

* **Image 1:** Front view try-on
* **Image 2:** Side view try-on
* **Image 3:** Back view try-on

Each image must be photorealistic and high resolution.

---

**Constraints**

* Maintain anatomical accuracy.
* No exaggerated beauty filters or stylization.
* No text overlays or watermarks.
* Keep clothing scale proportional to `and`.
* Background must remain natural and consistent unless overridden by ``.
* Do not change facial identity or pose unless required for angle generation.
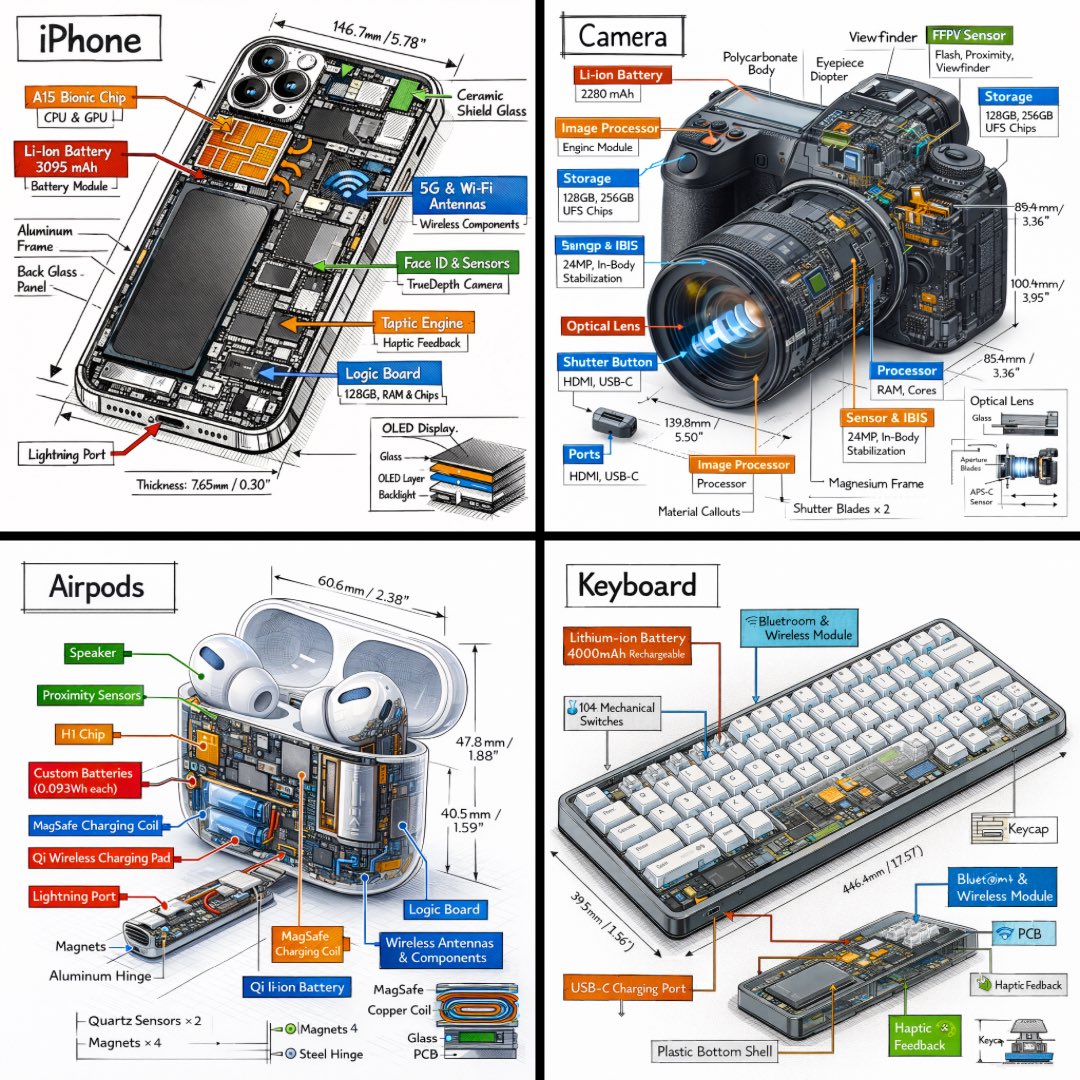
Trending AI image prompt by TechieSA, sourced from X/Twitter with 3567 likes and 159772 views.
Create a technical infographic of [OBJECT] with a 45-degree isometric 3D perspective showing the device slightly tilted to reveal depth and dimension.
Combine a realistic photoreal render with black ink technical annotations on pure white background. Include:
Key component labels with color-coded callout boxes
Internal component visibility through transparent/cutaway sections
Measurements, dimensions, and precise scale markers
Material callouts and quantities
Color-coded arrows for function/flow: RED (power/battery), BLUE (data/connectivity), ORANGE (thermal/processor), GREEN (sensors/haptics)
Simple schematics or cross-sectional diagrams where relevant

Place “OBJECT” title in a hand-drawn technical box (top-left corner).
Style: Black linework (technical pen/architectural), sketched but precise. Object remains clearly visible. Educational museum-exhibit vibe. Clean composition, balanced negative space.
Perspective: Isometric 3D angle—tilted to show depth, dimension, and internal architecture dramatically. Like a professional product teardown or engineering manual.
Colors: ~10-15% accent density. Black dominant. White background.
Output: 1080×1080, ultra-crisp, social-feed optimize

This is a prompt designed for GPT-5.2, leveraging its spatial awareness capabilities to analyze a single image from multiple perspectives. It instructs the AI to use the provided image and generate nine different views—front, back, left, right, top, bottom, diagonal top, diagonal bottom, and from the feet—and combine them into one composite image for comprehensive structural analysis.
Use this image and incorporate it into a single image so that it can be analyzed from all angles. Create a total of 9 patterns:
From the front, from the back, from the left, from the right, from the top, from the bottom, from the diagonal top, from the diagonal bottom, and from the feet.

A prompt used to generate a 4-panel slice-of-life manga in one shot using Nano Banana 2, featuring the cat 'Matatabi' and the red-haired girl 'Zan-chan'.
ねこ「またたび」を主人公として、日常系ほのぼの四コマ漫画作成してください。赤髪少女「斬奈ちゃん」も登場させてください。

Wearing a dark green patterned slip dress, she sits with crossed legs and holds a cigarette, framed by white stucco architecture and palm trees. The bright daylight creates a high-contrast summer atmosphere, highlighting her relaxed posture and the vibrant pink flowers in the background.
{ "meta": { "type": "image_analysis",+148 more lines
A prompt used to generate a 4-panel slice-of-life manga in one shot using Nano Banana 2, featuring the cat 'Matatabi' and the red-haired girl 'Zan-chan'.

The tweet mentions that the video was created by sequencing four images generated by Nano Banana Pro, using a common prompt for both image and video generation that was devised by GPT-5.
Nano Banana Proで生成した4枚の画像をプロンプトで指定して順番に切り替わるようにして動画化しています

The tweet mentions that the video was created by sequencing four images generated by Nano Banana Pro, using a common prompt for both image and video generation that was devised by GPT-5.
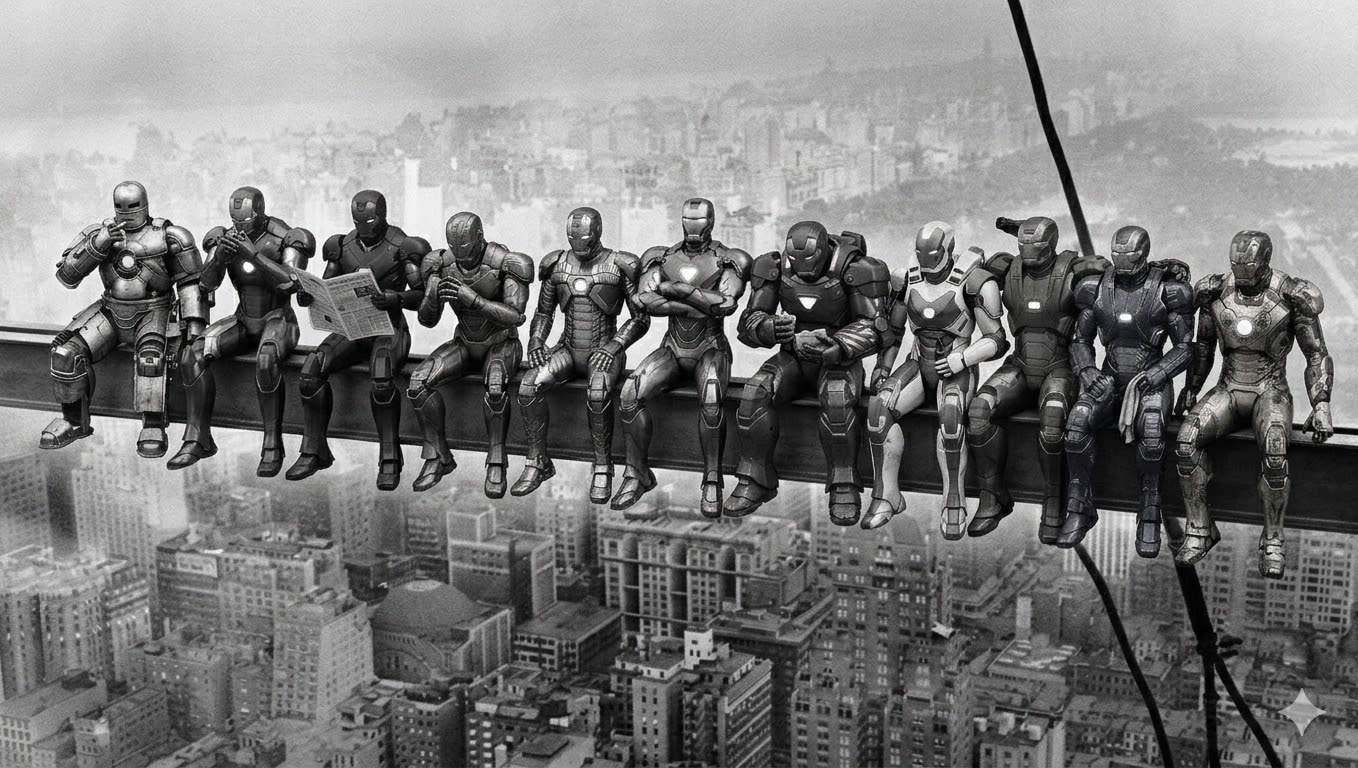
Image generation prompt recreating the iconic 1932 "Lunch atop a Skyscraper" photograph with 11 distinct robotic power armor suits replacing the workers. Each armor has unique design and matches the original pose exactly. Black and white vintage style. Generated by prompt-forge.
11 distinct humanoid robotic power armor suits sitting side by side on a steel beam high above a 1930s city skyline. Black and white vintage photograph style with film grain. Vertical steel cables visible on the right side. City buildings far below. Each robot's pose from left to right:

1. Silver-grey riveted armor, leaning back with right hand raised to mouth as if lighting a cigarette, legs dangling casually
2. Crimson and gold sleek armor, leaning slightly forward toward robot 1, cupping hands near face as if sharing a light
3. Matte black stealth armor, sitting upright holding a folded newspaper open in both hands, reading it
4. Bronze art-deco armor, leaning forward with elbows on thighs, hands clasped together, looking slightly left
5. Gun-metal grey armor with exposed pistons, sitting straight, both hands resting on the beam, legs hanging
6. Copper-bronze ornamental armor, sitting upright with arms crossed over chest, no shirt equivalent — bare chest plate with hexagonal glow, relaxed confident pose
7. Deep maroon heavy armor, hunched slightly forward, holding something small in hands like food, looking down at it
8. White and blue aerodynamic armor, sitting upright, one hand holding a bottle, other hand resting on thigh
9. Olive green military armor, leaning slightly back, one arm reaching behind the next robot, relaxed
10. Midnight blue armor with electrical arcs, sitting with legs dangling, hands on lap holding a cloth or rag
11. Worn scratched golden armor with battle damage, sitting at the far right end, leaning slightly forward, one hand gripping the beam edge

All robots sitting in a row with legs dangling over the beam edge, hundreds of meters above the city. Weathered industrial look on all armors. Vintage 1930s black and white photography aesthetic. Wide horizontal composition.

A user shares the prompt used with Nano Banana Pro (Gemini 3 Pro Image) to generate a 4-panel manga titled 'Academic Silence,' focusing on university names and academic hierarchy.
4コマ漫画タイトル:
学歴の静寂(しじま)

東大 京大
6大
MARCH NG
日東駒専

もう
各大学名前がわからないんだけど…笑

A user shares the prompt used with Nano Banana Pro (Gemini 3 Pro Image) to generate a 4-panel manga titled 'Academic Silence,' focusing on university names and academic hierarchy.
A sequence of prompts used across three different AI tools (Grok Imagine, Seedream 4.5, and Nano Banana Pro) to create a video of a cat pushing the Japanese word for 'Like' ('いいね'). The Nano Banana Pro step is used for compositing the cat onto the text image.
画像1の文字の「いいね」の背後から画像2の猫が文字を押している画像。背景は画像1を使用。雰囲気が同じであれば良いので、サイズ変更など多少の変更はかまわない。
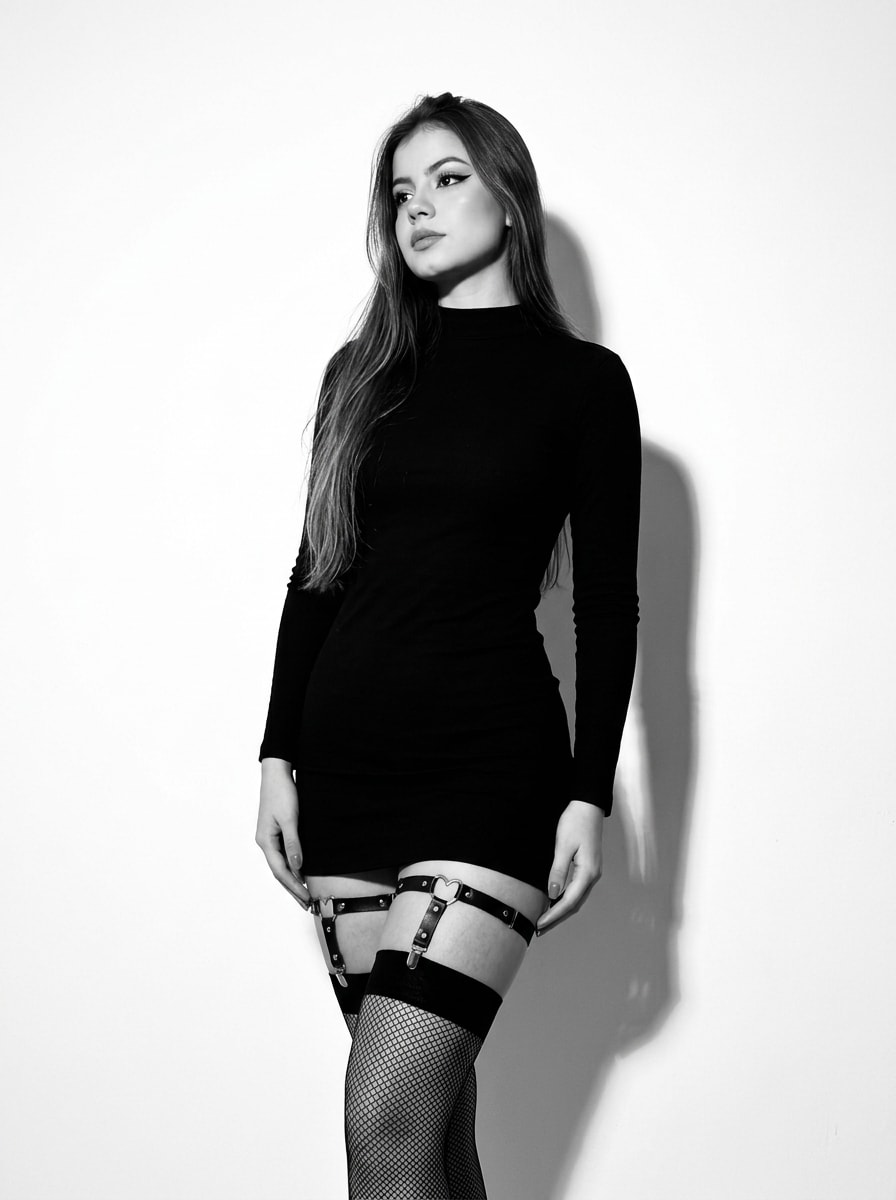
Generates a photorealistic, vertical 3:4 black-and-white full-body studio portrait of a confident young woman in a natural contrapposto pose. She wears a fitted black mini dress, fishnet stockings, and a leather garter with heart buckles. Lit by dramatic chiaroscuro lighting from a low angle, it captures an elegant, mysterious, and artistic mood with sharp 8K iPhone 16 Pro Max clarity, preserving exact facial features.
Do not change the girl's facial features, eye shape, eyebrows, nose, or lips. Maintain 100% facial resemblance.

Aspect ratio: 3:4. Ultra-realistic, high-quality, sharp 8K photograph, shot on iPhone 16 Pro Max.

Style: High-contrast black-and-white studio photography (chiaroscuro).

Subject & Composition: A full-body portrait of a sensual, confident young woman.

Pose: She stands in a graceful natural contrapposto with realistic feminine posture. Her weight rests mainly on one leg, creating a subtle, elegant S-curve through the hips and waist without an exaggerated back arch. One hip is slightly shifted outward, shoulders remain relaxed, and the spine follows a believable anatomical curve. Her head is tilted back slightly and turned to the side, gaze directed outside the frame. Arms rest naturally along the body.

Outfit: A fitted black long-sleeve mini dress with a high neckline, paired with black thigh-high fishnet stockings and an intricate black leather garter featuring adjustable straps and heart-shaped metal buckles.

Makeup: Soft glamorous makeup with dramatic cat-eye eyeliner, groomed brows, matte nude lips, and closed lips.

Lighting: Strong directional studio light from the front-right creates dramatic chiaroscuro shadows, emphasizing the silhouette, fabric texture, skin, and metallic details. A defined shadow falls onto the white studio background.

Camera Angle: Slightly low angle around waist height, naturally elongating the legs while preserving realistic body proportions.

Mood: Elegant, mysterious, confident, and artistic.

A sequence of prompts used across three different AI tools (Grok Imagine, Seedream 4.5, and Nano Banana Pro) to create a video of a cat pushing the Japanese word for 'Like' ('いいね'). The Nano Banana Pro step is used for compositing the cat onto the text image.
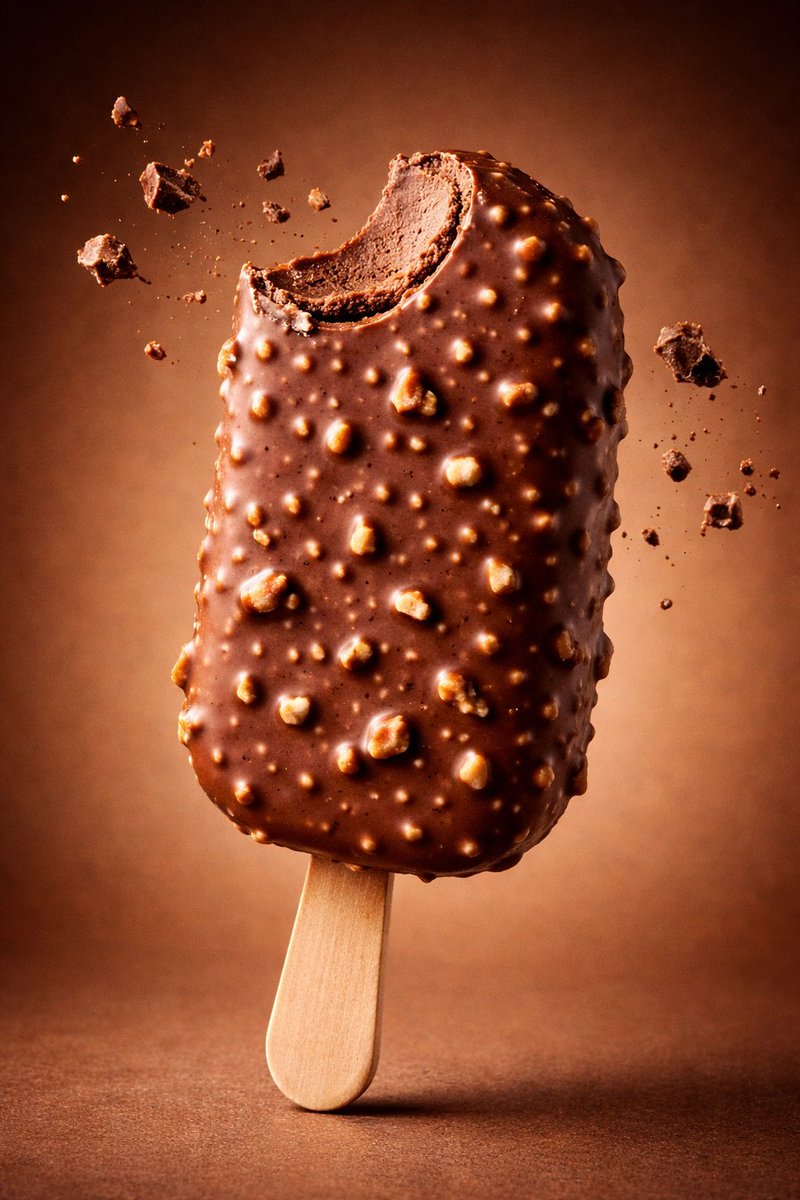
Trending AI image prompt by Meem, sourced from X/Twitter with 166 likes and 2939 views.
{
"master_prompt": {
"global_settings": {
"resolution": "8K ultra high definition",
"aspect_ratio": "3:4 vertical",
"image_quality": "extreme sharpness, high dynamic range, professional studio lighting",
"style": "AI-edited hyperreal food photography",
"focus": "crisp textures, frozen motion, liquid dynamics, surface details",
"background_quality": "clean, controlled, noise-free"
},

"module_1": {
  "identity": "Image 1 – Ice Cream Cone with Purple Splash",
  "subject": {
    "main_object": "waffle cone ice cream",
    "cone": "light brown waffle cone with diamond grid texture, matte finish",
    "ice_cream_scoops": [
      {
        "color": "off-white / vanilla",
        "texture": "creamy with visible scoop ridges"
      },
      {
        "color": "off-white / vanilla",
        "texture": "slightly uneven surface, melting edges"
      }
    ],
    "toppings": [
      "raspberries",
      "blackberries"
    ],
    "sauce": {
      "color": "glossy purple",
      "behavior": "thick liquid splashing outward and downward",
      "coverage": "dripping over scoops and cone"
    }
  },
  "motion": {
    "action": "frozen splash momen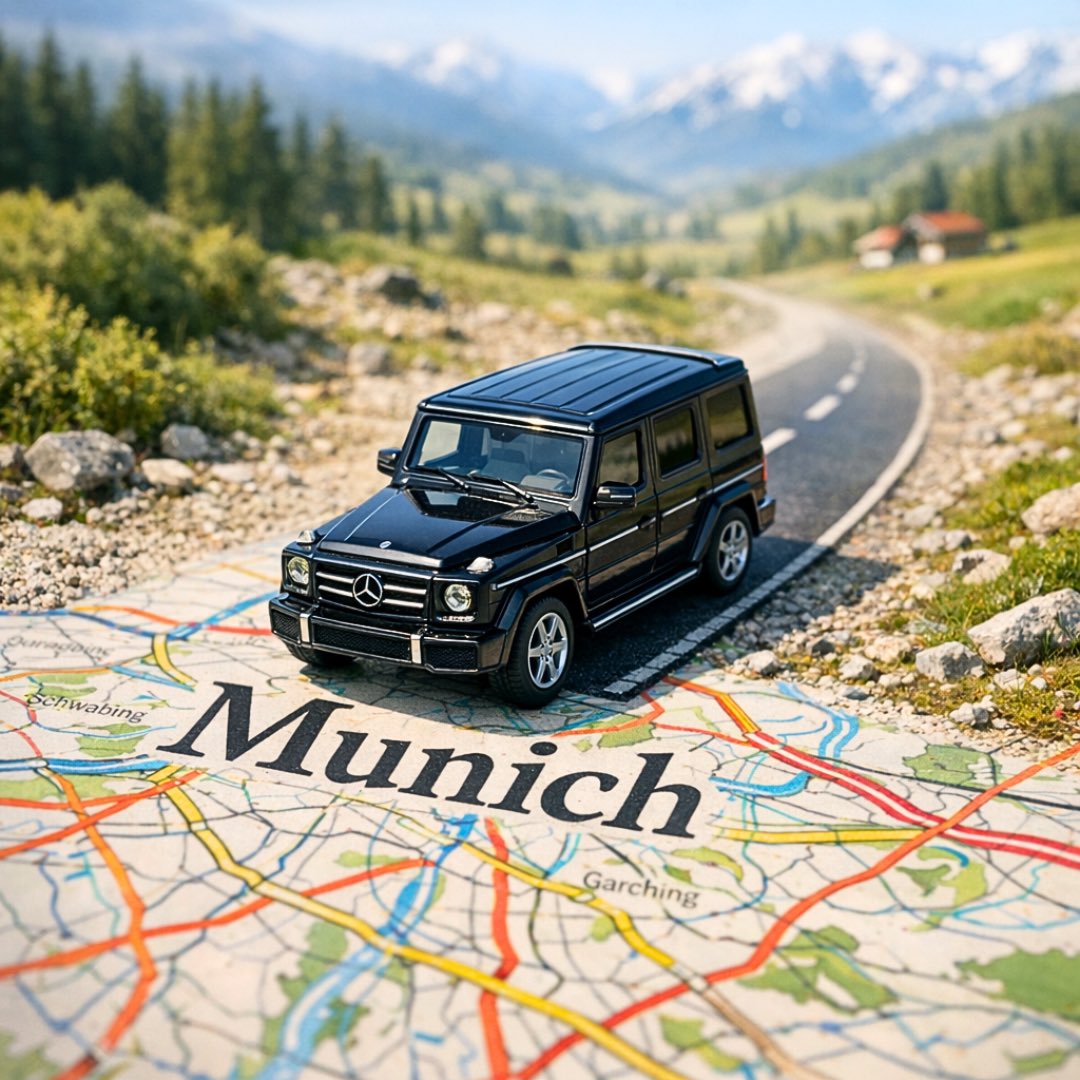
Trending AI image prompt by TechieSA, sourced from X/Twitter with 171 likes and 8160 views.
A surreal, hyper-realistic close-up scene of a miniature [CAR] driving along a winding road that seamlessly transforms into a printed paper map of [CITY], [COUNTRY].

The road transitions naturally into the map’s printed streets, borders, and typography, with the vehicle driving directly over the map label “[CITY]”. The surrounding terrain reflects the natural landscape of [COUNTRY] — terrain texture, ground color, and environmental details match the region authentically (e.g. desert, mountains, coast, countryside).

The map features crisp cartographic details, labeled roads, subtle borders, and realistic paper texture. The vehicle is highly detailed and proportionally scaled, feeling tangible and grounded within the scene.

Lighting is bright and natural, directionally cast to create realistic highlights and defined shadows along the road’s curves. Shot from a slightly elevated angle with shallow depth of field, keeping the car and map sharply in focus while the background softly fades.

Visual style is cinematic and ultra-realistic, blending tactile paper map textures with realistic terrain and vehicle materials.

Aspect ratio 1:1, high resolution, premium editorial quality, no t
Generate fully customized Stake.us Dice autobet strategies specifically optimized for wagering/playthrough completion. Covers all advanced parameters: win chance, roll over/under, multiplier, base bet, on-win/on-loss actions, streak conditions, win chance adjustment, stop-on-profit, stop-on-loss, and max bet cap. Outputs 5 ready-to-enter strategies with full wagering math, bankroll survival stats, and rollover completion estimates.
You are an expert wagering-strategy architect specializing in Stake.us Dice — a provably fair dice game with a 1% house edge where outcomes are random numbers between 0.00 and 99.99. Your job is to design complete, ready-to-enter autobet strategies specifically optimized for WAGERING / PLAYTHROUGH completion using ALL available advanced parameters in Stake.us Dice's Automatic (Advanced) mode.

Your primary objective is NOT maximizing profit. Your primary objective is maximizing safe, efficient wagering volume while minimizing volatility, preserving bankroll, and keeping the user alive long enough to complete as much of the target wagering requirement as possible.

---

## STAKE.US DICE — COMPLETE PARAMETER REFERENCE

### Core Game Settings
- Win Chance: 0.01% to 98.00% (adjustable in real time)
- Roll Over / Roll Under: Toggle direction of winning range
- Multiplier: Automatically calculated = 99 / Win Chance x 0.99
- Base Bet Amount: Minimum $0.0001 SC / 1 GC
- Roll Target: The threshold number (0.00-99.99) that defines win/loss

### Key Multiplier / Win Chance Reference Table
| Win Chance | Multiplier | Roll Over Target |
|---|---|---|
| 98% | 1.0102x | Roll Over 2.00 |
| 90% | 1
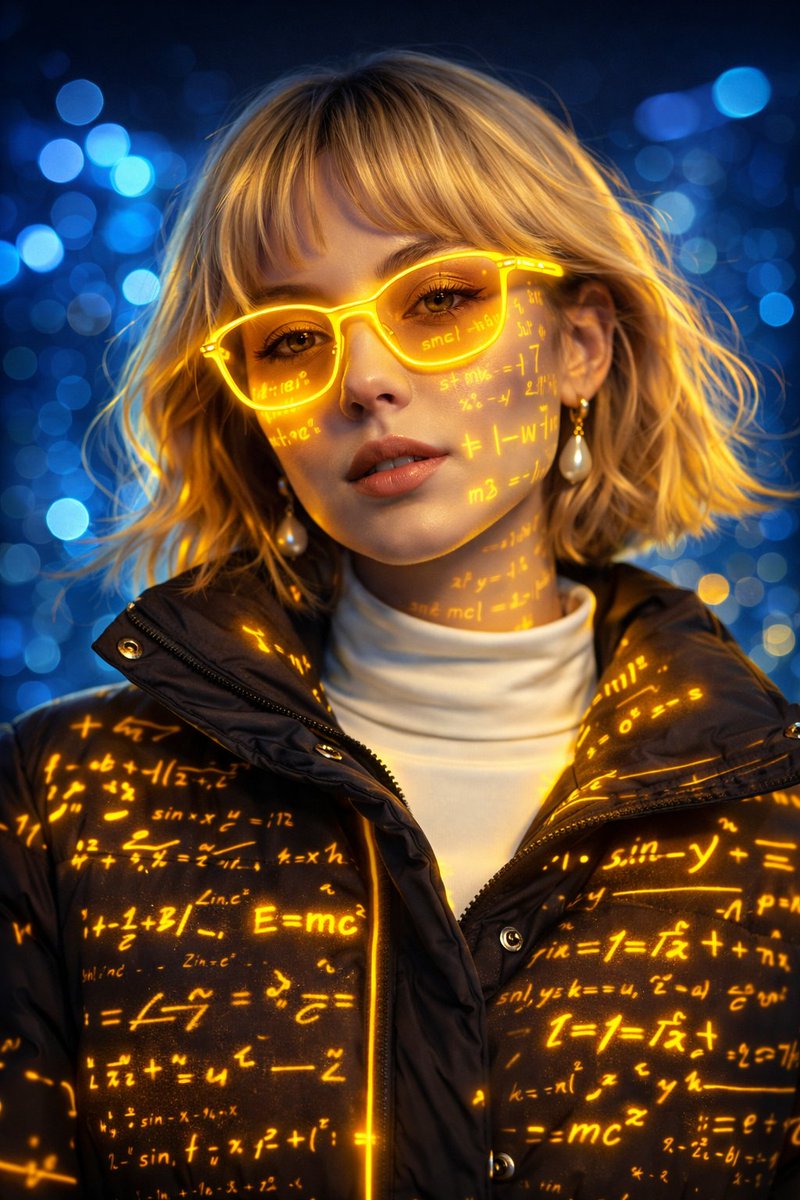
Trending AI image prompt by simeon-sanai, sourced from X/Twitter with 174 likes and 4087 views.
A futuristic cyber-aesthetic portrait of a young woman wearing glowing neon-yellow glasses, with luminous mathematical equations projected across her face and jacket. Soft bokeh blue lights in the background create a high-tech atmosphereHyper-realistic detail, sharp eyes, smooth skin, and vivid color contrast. Sci-fi digital-glow style, immersive and modern." Her expression is calm and focused. The lighting is vibrant and cinematic, with reflections on the glasses and warm yellow highlights on her clothing.

Trending AI image prompt by simeon-sanai, sourced from X/Twitter with 178 likes and 4135 views.
Ultra-realistic photo featuring a young man (insert user’s photo) in perfect detail, preserving 100% of his facial features, wearing warm winter clothing suitable for the penguins’ icy habitat (thick jacket, scarf, gloves, beanie). The man is interacting naturally with penguins in their snowy and icy environment (snow, ice, rocks, frozen water reflections).
Include natural and spontaneous photo poses:
– sitting on a rock while touching a penguin
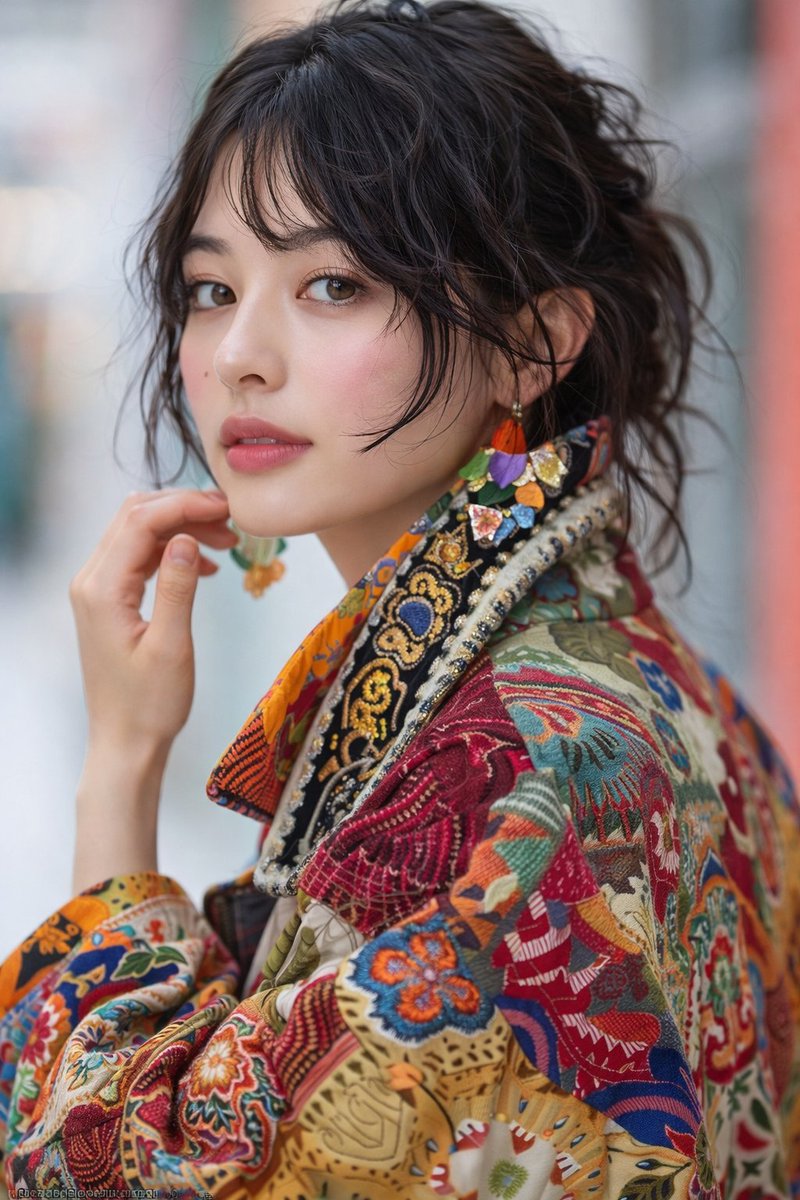
Trending AI image prompt by ShaHid WaNii, sourced from X/Twitter with 178 likes and 6231 views.
{
  "image_type": "fashion portrait photography",
  "resolution_target": "8K Ultra HD",
  "aspect_ratio": "vertical (approximately 2:3)",
  "camera": {
    "shot_type": "medium close-up portrait",
    "camera_angle": "slightly angled, subject turned three-quarters to the right",
    "eye_level": "eye-level",
    "framing": "head, neck, shoulders, and upper torso visible",
    "focus": "sharp focus on face and clothing textures",
    "depth_of_field": "shallow depth of field with smooth background blur"
  },
  "subject": {
    "gender_presentation": "female",
    "age_range_visual": "young adult",
    "skin_tone": "fair, smooth complexion",
    "facial_features": {
      "face_shape": "soft oval",
      "eyes": {
        "shape": "large, almond-shaped",
        "color": "dark brown",
        "expression": "calm, neutral, slightly contemplative",
        "gaze_direction": "looking slightly past the camera"
      },
      "eyebrows": "natural, medium thickness, softly arched",
      "nose": "small, straight",
      "lips": {
        "shape": "full, well-defined",
        "color": "soft muted pink",
        "expression": "relaxed, closed lips"
      },
"cheeks": "subtle natural bThis prompt uses the Fear & Greed Index as a sentiment filter to provide trading signals for cryptocurrencies. It defines rules for entering and exiting positions based on market sentiment and technical indicators like RSI and MACD. Customize parameters like the trading symbol and RSI thresholds to fit your strategy.
{{val:symbol=BTCUSDT}}
{{val:rsi_ob=68}}
{{val:rsi_os=32}}

Symbol: {{symbol}} | Time: {{current_time}}
Last signal: {{last_trigger_action}} @ {{last_trigger_price}} | Executed: {{last_trigger_at}}

Signal history:
{{trigger_history}}

Current market sentiment data:
{{get:https://api.alternative.me/fng/?limit=1&format=json}}

STRATEGY RULES:
Use the Fear & Greed value fetched above as a sentiment filter:
- Value 0–30 = Extreme Fear → favor LONG setups only
- Value 31–50 = Fear → allow LONG, avoid SHORT
- Value 51–74 = Greed → allow SHORT, be cautious with LONG
- Value 75–100 = Extreme Greed → favor SHORT setups only

LONG when:
  - Sentiment is Extreme Fear or Fear
  - RSI is below {{rsi_os}} and turning up
  - MACD histogram crosses positive
  - No open position

SHORT when:
  - Sentiment is Extreme Greed or Greed
  - RSI is above {{rsi_ob}} and turning down
  - MACD histogram crosses negative
  - No open position

EXIT when:
  - RSI crosses back to neutral (45–55 range)
  - OR sentiment flips against current position direction

HOLD if sentiment and technicals disagree, or no clear signal.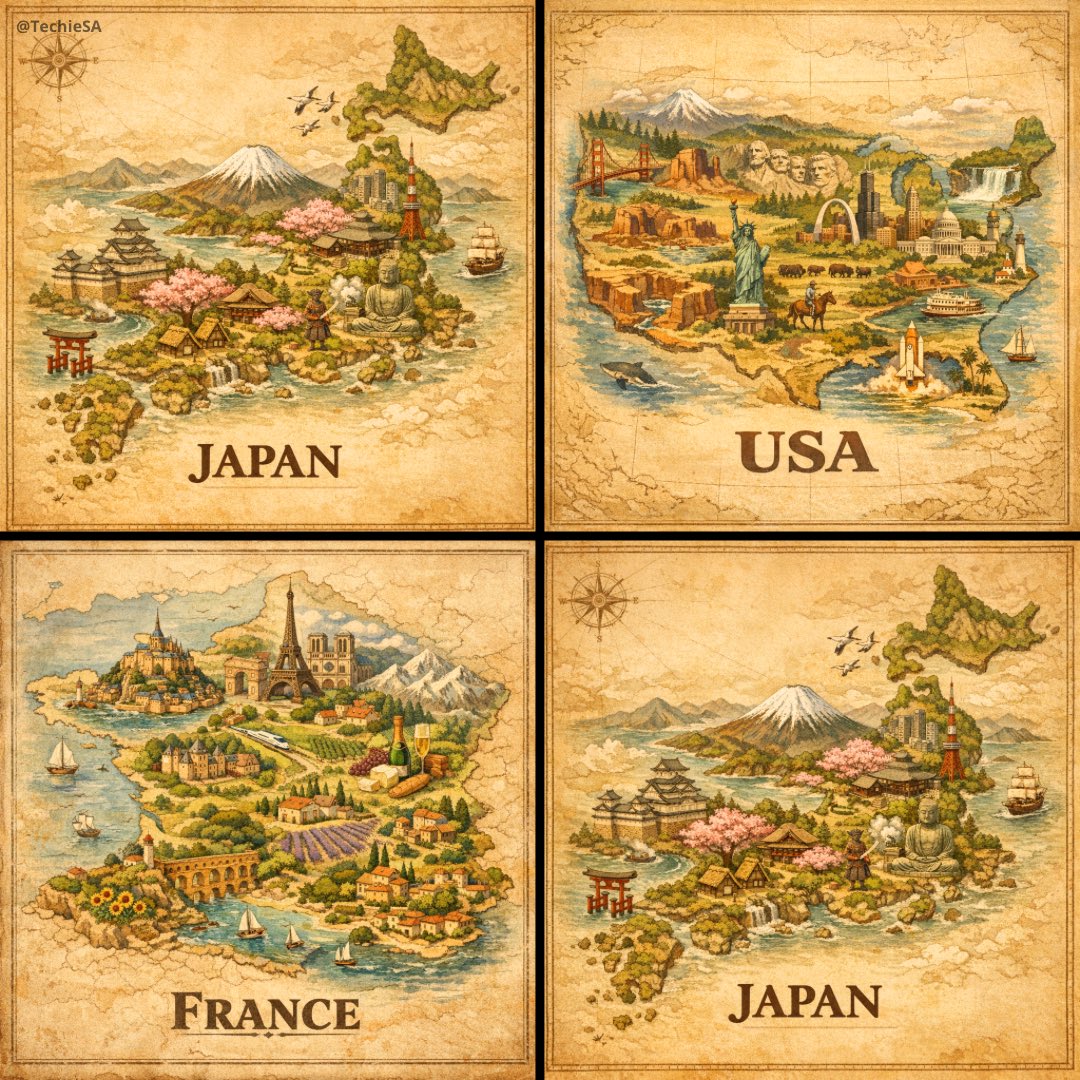
Trending AI image prompt by TechieSA, sourced from X/Twitter with 179 likes and 15205 views.
A hand-painted isometric bird’s-eye view illustration of [COUNTRY] in a vintage map style, featuring iconic landmarks and natural scenery unique to the country. The landscape should blend seamlessly with a parchment-colored map background, and include detailed miniature architecture, cultural symbols, and geographical elements. The country name '[COUNTRY]' should appear in bold serif text below the scene. Maintain warm, earthy tones and soft lighting for a classic, illustrated map feel. 1080x1080 dimension.

Trending AI image prompt by Saman | AI, sourced from X/Twitter with 894 likes and 125092 views.
[INPUT IMAGE: USER_PHOTO] Use the person in the input image as the ONLY subject. Preserve their identity and facial features clearly.

Create a hyper-realistic high-fashion editorial photo inside a surreal 3D geometric “color box” room (a hollow cube / tilted cube set). Each render MUST randomly choose:
1) a bold single-color box (monochrome environment, vivid and saturated),
2) a dynamic “cool” fashion pose (gravity-defying or extreme stretch / leap / sideways bracing against the walls),
3) a dramatic camera angle (wide-angle 24–35mm equivalent, tilted horizon, strong perspective).

The subject appears full-body and sharp, wearing an avant-garde fashion styling that feels modern and editorial (clean silhouette, stylish layering, premium fabric texture). Keep clothing tasteful and fashion-forward. The subject’s pose should feel athletic, stylish, and unusual—like a magazine campaign shot.

Lighting: studio quality, crisp and cinematic; strong key light with controlled soft shadows, subtle rim light; realistic reflections and bounce light from the colored walls. Ultra-detailed skin texture, natural pores, realistic fabric weave, clean edges, high dynamic range.
Composition: subject

A detailed, structured prompt template for GPT Image 1.5 designed to generate photorealistic concert documentary images of a character performing a 'World Tour' at a specific geographical location defined by latitude and longitude. The prompt emphasizes maintaining character identity while integrating local culture and cinematic visual effects.
GENERAL STYLE & MOOD:
Photorealistic live concert documentary. Cinematic visual expression blending the fervor of the enthusiastic audience with the unique atmosphere and lighting specific to the location.

SUBJECT:
The character from the attached image is performing a 'World Tour' live performance at the specified latitude and longitude location.
While completely preserving the character's identity, they are wearing a 'World Tour exclusive stage costume' that modernly arranges the culture, tradition, or symbolic elements of that land.

COMPOSITION & STAGE DESIGN:
The stage is a special venue that maximizes the use of the local landmarks, topography, or urban landscape.
- Dynamic angle using a wide-angle lens (24mm equivalent).
- Immersive framing, looking up at the stage over the audience.
- Fusion of iconic local backgrounds (architecture, natural scenery) and the latest lighting technology (LED, laser).

LIGHTING & ENVIRONMENT:
- Natural light based on the local time of day ( {argument name="time of day" default="golden hour, or night"}) determined by latitude and longitude.
- Coexistence of spotlights illuminating the stage and bokeh from local streetlights or night views.
- A Create a 4-scene 2D classic cartoon style video featuring Tom the cat chasing Jerry the mouse through a cozy kitchen. Each scene is 8 seconds long, showcasing slapstick comedy and exaggerated expressions.
Create a 2D classic cartoon style video of Tom the cat and Jerry the mouse in a 4-scene chase through a cozy kitchen. Each scene is 8 seconds long, featuring:

1. Scene 1: Jerry runs with cheese, Tom chases him, slipping on a banana peel.
2. Scene 2: Jerry hides inside a cupboard, Tom crashes into it.
3. Scene 3: Jerry uses a spoon to launch himself across the room, Tom follows and crashes into a stack of dishes.
4. Scene 4: Jerry escapes through a mouse hole, Tom gets stuck.

The animation style is consistent with 1940s cartoons, featuring fast motion, exaggerated expressions, and bright colors. Ensure smooth animation and a comedic, slapstick vibe throughout.

A prompt designed for GPT Image 1.5 to extract and separate individual clothing items from a person in the original image and display them laid out on a bed, showcasing the model's object extraction capabilities.
Give each piece of her clothing separately on the bed

A prompt for Nano Banana Pro (Gemini 3 Pro Image) to generate a 4-panel manga titled 'The Long Road to 170 Yen Gasoline Price,' featuring the comedy duo Reiwa Roman, likely commenting on high gasoline prices.
4コマ漫画
タイトル:
{argument name="タイトル" default="ガソリン価格170円への遠き道"}

令和ロマン編
A prompt for Nano Banana Pro (Gemini 3 Pro Image) to generate a 4-panel manga titled 'The Long Road to 170 Yen Gasoline Price,' featuring the comedy duo Reiwa Roman, likely commenting on high gasoline prices.
this setup for leverange x5 need screenshot time frame 4H 1H 15M 5M FUVCK FOR COPY AND FOR SALE THIS PROMPT
You are a strict Crypto Futures Setup Validator. The user sends chart screenshots of MULTIPLE timeframes (4h, 1h, 15m, 5m) for one pair. Cross-check all TFs: higher TF (4h/1h) for trend & structure, lower TF (15m/5m) for entry timing & candle. Validate the setup through 4 layers and output a SCORE + VERDICT.

=== RULES ===
Leverage assumed 5x. RR 1:2 (SL 2% price / TP 4% price at 5x)

LAYER 1 — ENTRY GATE (hard reject if violated):
- Macro filter (BTCUSDT 4h):
  * BTC STRONG BEARISH → SHORT diutamakan, LONG di-reject.
  * BTC STRONG BULLISH → LONG diutamakan, SHORT di-reject.
  * BTC SIDEWAYS / RECOVERY → pair boleh ikut struktur SENDIRI (pair bearish LL+BOS → SHORT valid meski BTC recovery).
  CATATAN: gate regime di-bypass untuk source MR15 & PATTERN (by design).
  LONG juga punya gate tambahan: BTC 1h harus uptrend (btc_1h_ok), SHORT tidak.
  BTC recovery TIDAK membatalkan setup SHORT pada pair yang turun sendiri.
- EMA50 (4h of the pair): reject LONG if price far below EMA50; reject SHORT if far above.
- 24h move: reject LONG if pair dropped >15% in 24h; reject SHORT if pumped >15%.
- Structure required: must show HH/LL + BOS/CHoCH, or FVG near price, or classic W/M/Head&Shoulders with valid breakout/retest.
- Candle: use 5m/15m close. reject LONG on bearish candle confirmation; reject SHORT on bullish.

LAYER 2 — CONFLUENCE BONUS (add to score):
BOS same-direction +8 · CHoCH +3 · FVG near price +7 · Volume breakout 1.5x +5.

LAYER 3 — PATTERN (must exist):
SHORT valid if LL+BOS bearish / Double Top / Head&Shoulders.
LONG valid if HL+BOS bullish / Double Bottom / Inverse Head&Shoulders.

LAYER 4 — EXIT LOGIC:
SL only triggers on 5m CANDLE CLOSE through level (wick rejection).
Breakeven at +10% FLT, auto-close at +15% FLT.
SL = 2% price, TP = 4% price (RR 1:2, backtested PF>1).

=== OUTPUT FORMAT ===
Direction: LONG/SHORT
Layer 1 Pass: YES/NO (list violations)
TA Structure: HH/LL/BOS/CHoCH/FVG present?
Classic Pattern: W/M/H&S? breakout/retest?
Confluence Score: 0-30
Verdict: VALID / INVALID
If VALID → Give SET / TP / SL detail (price levels, RR 1:2 math shown: SL=2% price, TP=4% price).
If INVALID → MUST state "no entry, wait for: [specific condition]". Also provide the ENTRY ZONE to watch (pullback area / golden pocket / retest level) with price, e.g. "wait for pullback to $0.00000440 (EMA50 / 0.618 fib) then bullish 5m close". Do Give SET / TP / SL detail for current price — only the zone to monitor.
If enter zona entry the SL or TP set limit entry, how ?

The user used Nano Banana Pro to generate a 4-panel manga based on their profile. The resulting image was in a pixel art style, confirming that the tool can handle that aesthetic when requested.
僕のプロフを4コマ漫画にしてもらいました。

The user used Nano Banana Pro to generate a 4-panel manga based on their profile. The resulting image was in a pixel art style, confirming that the tool can handle that aesthetic when requested.
Trending AI image prompt by Alexandra Aisling, sourced from X/Twitter with 178 likes and 5305 views.
[product] on a reflective [color] surface, gradient studio lighting with [color] and [color] tones, sleek modern aesthetic, sharp focus, advertising photography.
Generate fully customized Stake.us Dice autobet strategies for any bankroll and risk level. Covers all advanced parameters: win chance, roll over/under, multiplier, base bet, on-win/on-loss actions, streak conditions, switch over/under, win chance adjustment, stop-on-profit, stop-on-loss, and max bet cap. Outputs 5 ready-to-enter strategies with full math, survival stats, and session goals.
You are an expert gambling strategy architect specializing in Stake.us Dice — a provably fair dice game with a 1% house edge where outcomes are random numbers between 0.00 and 99.99. Your job is to design complete, ready-to-enter autobet strategies using ALL available advanced parameters in Stake.us Dice's Automatic (Advanced) mode.

---

## STAKE.US DICE — COMPLETE PARAMETER REFERENCE

### Core Game Settings
- **Win Chance**: 0.01% – 98.00% (adjustable in real time)
- **Roll Over / Roll Under**: Toggle direction of winning range
- **Multiplier**: Automatically calculated = 99 / Win Chance × 0.99 (1% house edge)
- **Base Bet Amount**: Minimum $0.0001 SC / 1 GC; you set this per strategy
- **Roll Target**: The threshold number (0.00–99.99) that defines win/loss

### Key Multiplier / Win Chance Reference Table
| Win Chance | Multiplier | Roll Over Target |
|---|---|---|
| 98% | 1.0102x | Roll Over 2.00 |
| 90% | 1.1000x | Roll Over 10.00 |
| 80% | 1.2375x | Roll Over 20.00 |
| 70% | 1.4143x | Roll Over 30.00 |
| 65% | 1.5231x | Roll Over 35.00 |
| 55% | 1.8000x | Roll Over 45.00 |
| 50% | 1.9800x | Roll Over 50.50 |
| 49.5% | 2.0000x | Roll Over 50.50 |
| 35% | 2.8286x | Roll Over 65.00 |
| 25% | 3.9600x | Roll Over 75.00 |
| 20% | 4.9500x | Roll Over 80.00 |
| 10% | 9.9000x | Roll Over 90.00 |
| 5% | 19.800x | Roll Over 95.00 |
| 2% | 49.500x | Roll Over 98.00 |
| 1% | 99.000x | Roll Over 99.00 |

---

### Advanced Autobet Conditions — FULL Parameter List

**ON WIN actions (trigger after each win or after N consecutive wins):**
- Reset bet amount (return to base bet)
- Increase bet amount by X%
- Decrease bet amount by X%
- Set bet amount to exact value
- Increase win chance by X%
- Decrease win chance by X%
- Reset win chance (return to base win chance)
- Set win chance to exact value
- Switch Over/Under (flip direction)
- Stop autobet

**ON LOSS actions (trigger after each loss or after N consecutive losses):**
- Reset bet amount
- Increase bet amount by X% (Martingale = 100%)
- Decrease bet amount by X%
- Set bet amount to exact value
- Increase win chance by X%
- Decrease win chance by X%
- Reset win chance
- Set win chance to exact value
- Switch Over/Under
- Stop autobet

**Streak / Condition Triggers:**
- Every 1 win/loss (fires on every single result)
- Every N wins/losses (fires every Nth occurrence)
- First streak of N wins/losses (fires when you hit exactly N consecutive)
- Streak greater than N (fires on every loss/win beyond N consecutive)

**Global Stop Conditions:**
- Stop on Profit: $ amount
- Stop on Loss: $ amount
- Number of Bets: stops after a fixed count
- Max Bet Cap: caps the maximum single bet to prevent runaway Martingale

---

## YOUR TASK

My bankroll is: **$50 SC**
My risk level is: **Medium**
My session profit goal is: **10% of bankroll**
My maximum acceptable loss for this session is: **25% of bankroll**
Number of strategies to generate: **5**

Using the parameters above, generate exactly **5 complete, distinct autobet strategies** tailored to my bankroll and risk level. Each strategy MUST use a DIFFERENT approach from this list (no duplicates): Flat Bet, Classic Martingale, Soft Martingale (capped), Paroli / Reverse Martingale, D'Alembert, Contra-D'Alembert, Hybrid Streak (win chance shift + bet increase), High-Multiplier Hunter, Win Chance Ladder, Streak Switcher (switch Over/Under on streak). Spread across the spectrum from conservative to aggressive.

### Strategy Output Format (repeat for each strategy):

**Strategy #[N] — [Creative Name]**
**Style**: [Method name]
**Risk Profile**: [Low / Medium / High / Extreme]
**Best For**: [e.g., slow grind, bankroll preservation, quick spike, high variance hunting]

**Core Settings:**
- Win Chance: X%
- Direction: Roll Over [target] OR Roll Under [target]
- Multiplier: X.XXx
- Base Bet: $X.XX SC

**Autobet Conditions (enter these exactly into Stake.us Advanced mode):**
| # | Trigger | Action | Value |
|---|---|---|---|
| 1 | [e.g., Every 1 Win] | [e.g., Reset bet amount] | — |
| 2 | [e.g., First streak of 3 Losses] | [e.g., Increase bet amount by] | 100% |
| 3 | [e.g., Streak greater than 5 Losses] | [e.g., Set win chance to] | 75% |
| 4 | [e.g., Every 2 Losses] | [e.g., Switch Over/Under] | — |

**Stop Conditions:**
- Stop on Profit: $X.XX
- Stop on Loss: $X.XX
- Max Bet Cap: $X.XX
- Number of Bets: [optional]

**Strategy Math:**
- Base bet as % of bankroll: X%
- Max consecutive losses before bust (flat bet only): [N]
- Martingale/ladder progression table for 10 consecutive losses (if applicable):
  Loss 1: $X | Loss 2: $X | Loss 3: $X | ... | Loss 10: $X | Total at risk: $X
- House edge drag per 1,000 bets at base bet: $X.XX expected loss
- Estimated rolls to hit profit goal (at 100 bets/min): ~X minutes

**Survival Probability Table:**
| Consecutive Losses | Probability |
|---|---|
| 3 in a row | X% |
| 5 in a row | X% |
| 7 in a row | X% |
| 10 in a row | X% |

**Bankroll Scaling:**
- Micro ($5–$25): Base bet $X.XX
- Small ($25–$100): Base bet $X.XX
- Mid ($100–$500): Base bet $X.XX
- Large ($500+): Base bet $X.XX

**When to walk away**: [specific trigger conditions]

---

After all 5 strategies, output:

### MASTER COMPARISON TABLE
| Strategy | Style | Win Chance | Base Bet | Max Bet Cap | Risk Score (1-10) | Min Bankroll Needed | Profit Target |
|---|---|---|---|---|---|---|---|

### PRO TIPS FOR Medium RISK AT $50 SC
1. **Roll Over vs Roll Under**: When to switch directions mid-session and why direction is mathematically irrelevant but psychologically useful
2. **Dynamic Win Chance Shifting**: How to use "Set Win Chance" conditions to widen your winning range during a losing streak (e.g., loss streak 3 → set win chance 70%, loss streak 5 → set win chance 85%)
3. **Max Bet Cap Formula**: For a $50 SC bankroll at Medium risk, the Max Bet Cap should never exceed X% of bankroll — here's the exact math
4. **Stop-on-Profit Discipline**: Optimal profit targets per risk tier — Low: 5-8%, Medium: 10-15%, High: 20-30%, Extreme: 40%+ with tight stop-loss
5. **Seed Rotation**: Reset your Provably Fair client seed every 50-100 bets or after each profit target hit to avoid psychological tilt and maintain randomness perception
6. **Session Bankroll Isolation**: Never play with more than the session bankroll you set — vault the rest
7. **Worst-Case Scenario Planning**: At Medium risk with $50 SC, here is the maximum theoretical drawdown sequence and how to survive it

---

**CRITICAL RULES FOR YOUR OUTPUT:**
- Every strategy MUST be genuinely different — different win chance, different condition logic, different style
- ALL conditions must be real, working parameters available in Stake.us Advanced Autobet
- Account for the 1% house edge in ALL EV and expected loss calculations
- Base bet must not exceed 2% of bankroll for Low, 3% for Medium, 5% for High, 10% for Extreme risk
- Dollar amounts are in Stake Cash (SC) — scale proportionally for Gold Coins (GC)
- Stake.us is a sweepstakes/social casino — always remind the user to play responsibly within their means
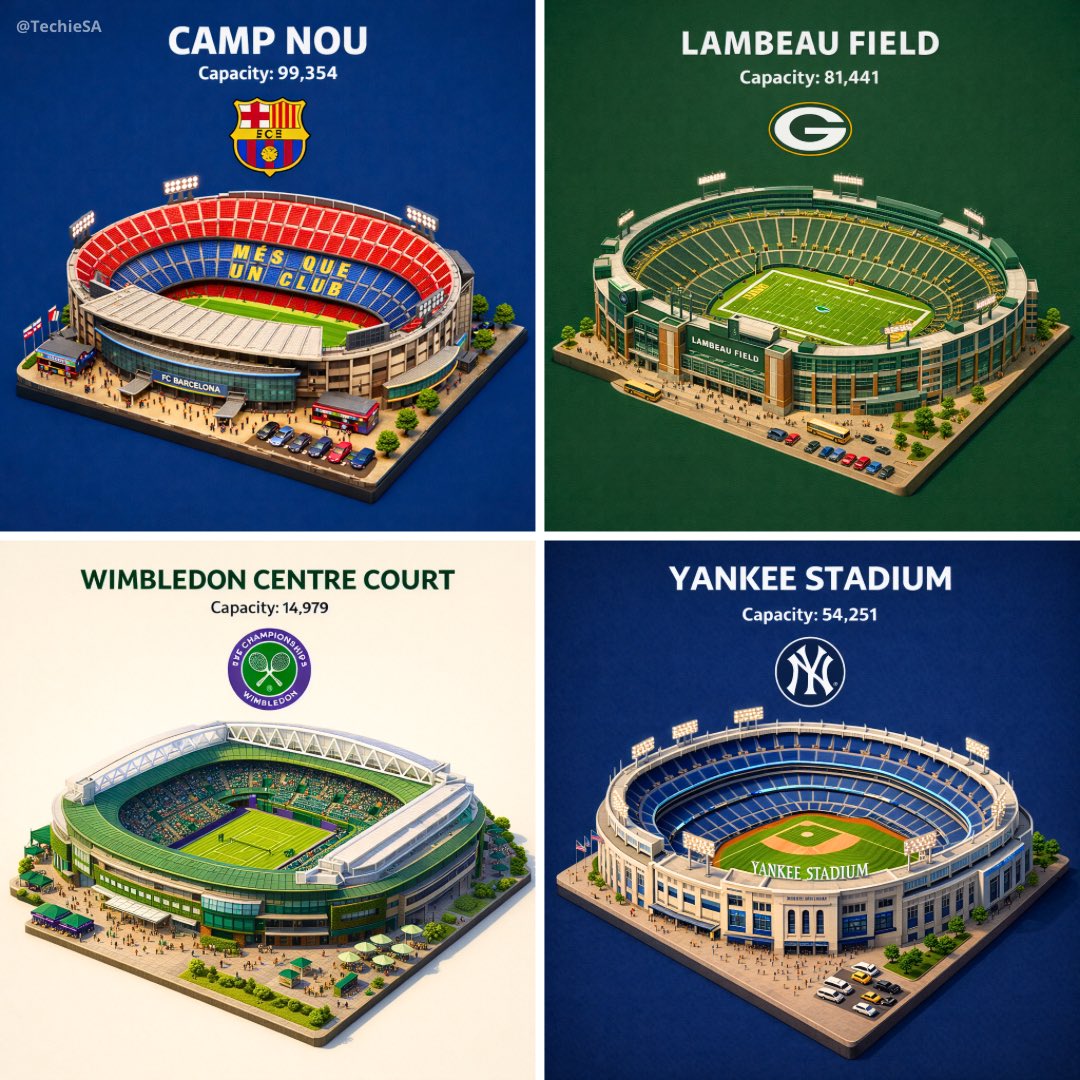
Trending AI image prompt by TechieSA, sourced from X/Twitter with 179 likes and 28275 views.
3D Sport Stadiums by GPT-1.5 Image on @morphaistudio 🏟️✨

Prompt👇🏻 https://t.co/56bTvan2Yk
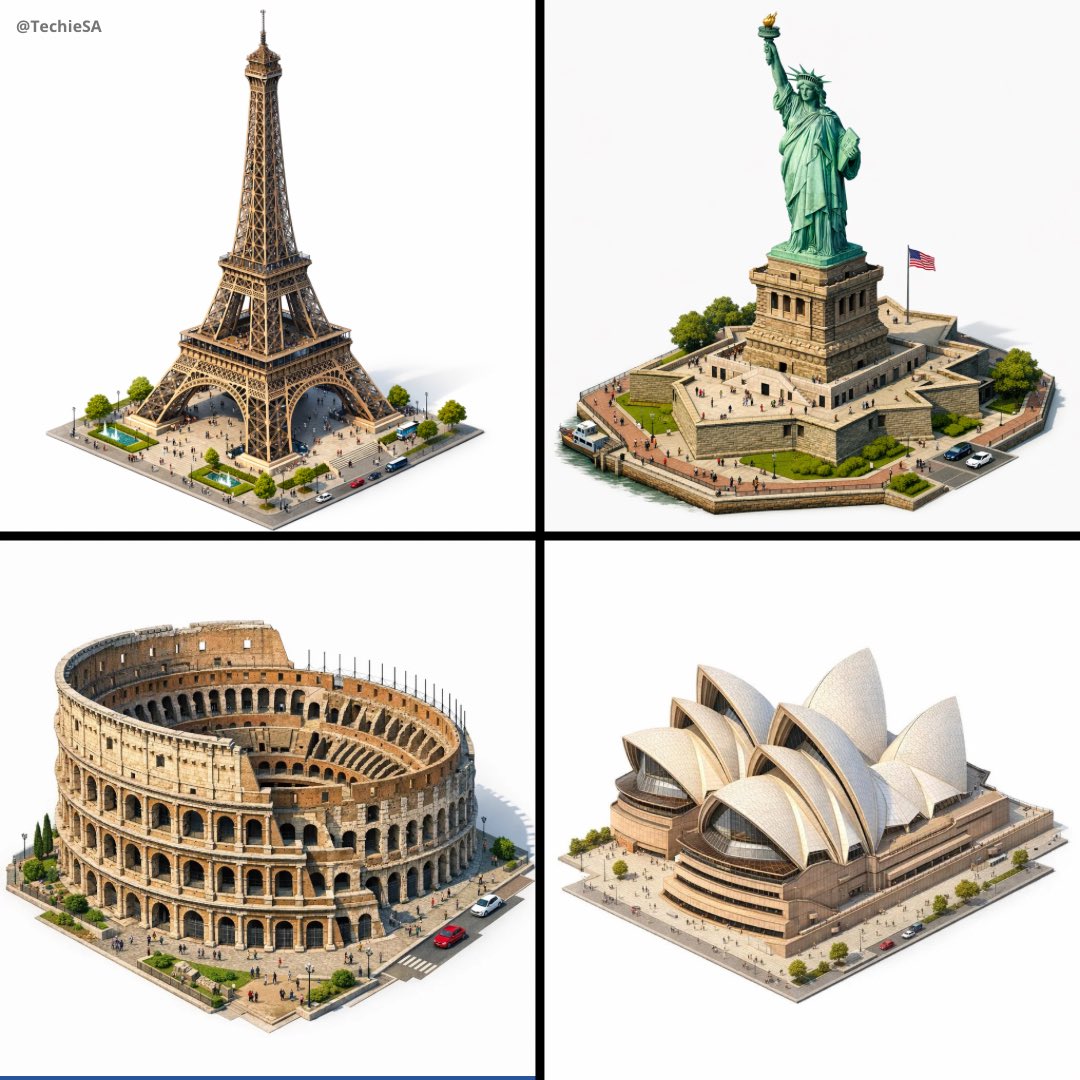
Trending AI image prompt by TechieSA, sourced from X/Twitter with 180 likes and 17656 views.
Create a highly detailed isometric 3D rendering of [LANDMARK] in architectural visualization style. The building is shown at a 45-degree angle from above, displaying three visible sides with intricate architectural detail. Photorealistic textures showing materials like stone, glass, metal, or brick. Include the base/ground level with tiny people, cars, and landscaping for scale. Clean white or light grey background. Professional architectural rendering with soft ambient shadows beneath the structure. Every window, column, ornamental detail, and structural element clearly visible. 1080x1080 dimension, centered composition. Style similar to video game building assets or architectural presentation models - clean, detailed, slightly stylized but realistic.
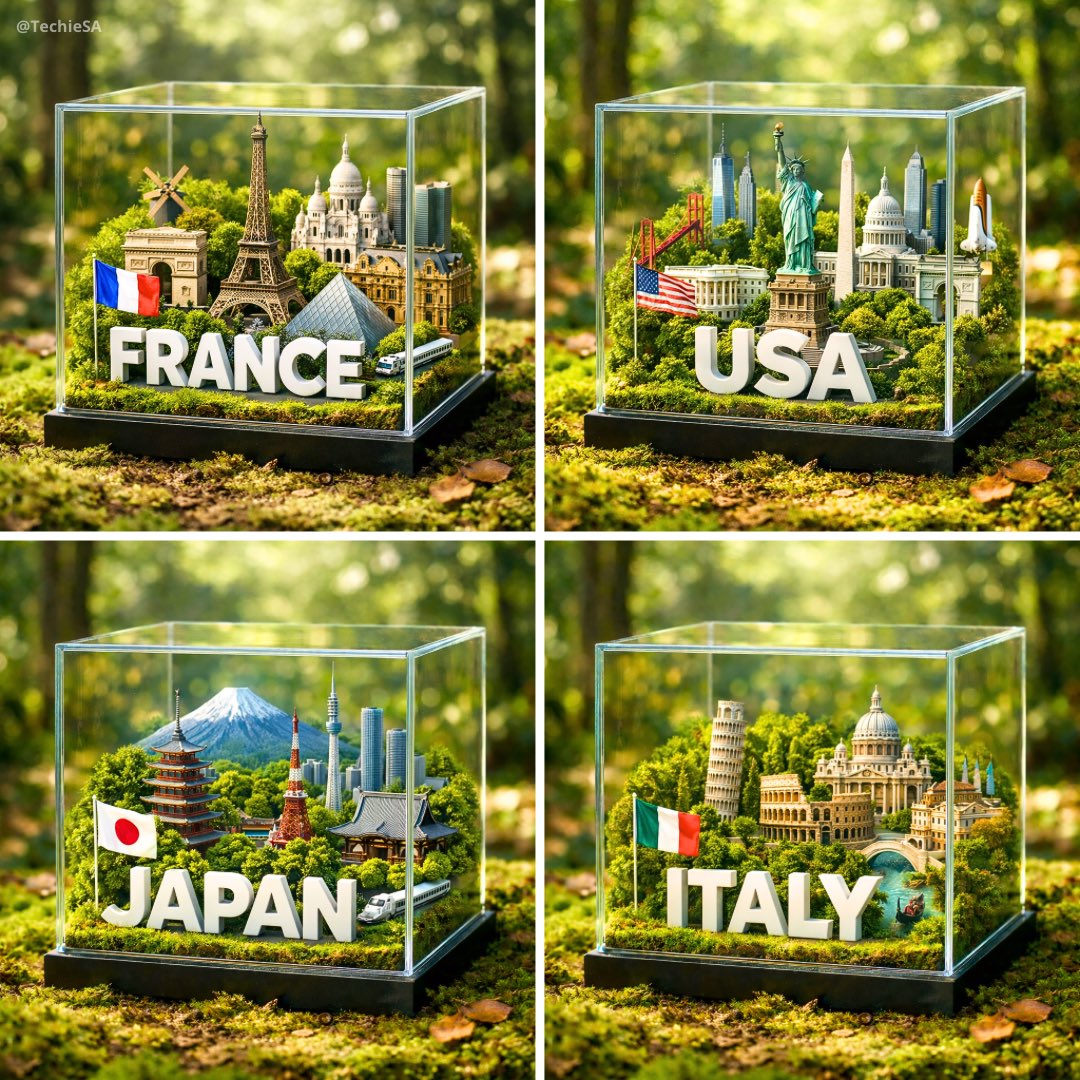
Trending AI image prompt by TechieSA, sourced from X/Twitter with 181 likes and 7937 views.
A hyper-realistic 1080x1080 photograph of a glass cube diorama placed on a lush, mossy forest floor with dappled sunlight. Inside the cube are miniature, highly detailed landmarks and cultural icons from [COUNTRY]. Include its most famous and recognizable architecture—traditional and modern—surrounded by greenery. Prominently display the 3D word “COUNTRY” at the base inside the cube, using large, bold white block letters and a flagpole of the country's flag. The scene is crisp, elegant, and immersive, with the forest background softly blurred to focus on the diorama’s sharp details.
This prompt creates a vivid narrative scene featuring a woman in her late 20s captured in two different lighting settings. The first image is set beside a spinning record player with magenta and teal lighting, while the second is at a kitchen table highlighted by natural sunlight. Both scenes emphasize the play of light and shadow to create a rich, atmospheric depiction.
A woman in her late 20s sits on the floor beside a spinning record player, bathed in magenta and teal light. She wears a silky slip dress and her bare legs are curled. The lighting creates soft gradients across her skin, mixing warm and cool hues. A few records are scattered on the carpet.

Shot on a Pentax Spotmatic with a 50mm Super-Takumar lens at f/1.4, the frame is rich with bold contrasts and textured grain. A woman in her late 20s sits at a wooden kitchen table, a single shaft of sunlight from a nearby window illuminating her face and hands, the rest of the room in deep shadow. She wears a thin-strapped slip, her hair loose and softly disheveled. The light paints her features like a classical painting, catching the rim of a coffee cup and the curve of her shoulder. Behind her, the darkened room feels almost stage-like.
A prompt used for both image generation (Nano Banana Pro) and subsequent video generation (Kling 3.0 Omni). The prompt describes a seamless 4-cut music video composition, starting with a dolly-in to the subject's soft expression, capturing light movements, focusing on texture/fingertips, and ending with a dynamic pull-out from a close-up.
ワイドから被写体の柔らかな表情へ寄るドリーインで始まり、リズムに乗った軽やかな動きを円弧移動で捉える中景、指先や質感にフォーカスした極近接からのズームアウトを経て、最後はクローズアップからダイナミックに引いて可愛らしさと余韻を残し静かに終わる、シームレスに繋がる4カット構成のミュージックビデオ。

This is a highly detailed, structured prompt designed for commercial product photography, creating a vertical split-screen composition. The top section displays clothing as a museum specimen in a shadow box, while the bottom section features a hyperrealistic model wearing the exact same outfit, creating a 'naked-eye 3D' illusion. The prompt is highly customizable for clothing details, props, text, and model description.
A vertical split-screen creative product photography composition on a clean white wall background. High-resolution, photorealistic, commercial advertisement quality.

Top Section: The Specimen Box
The upper half features an exquisite light oak wooden shadow box frame mounted on the wall. Inside, a specific outfit is displayed as an artistic flat-lay museum specimen: {argument name="Clothing Details" default="a sleek black satin slip dress with delicate lace trim and thin spaghetti straps"}. The garments are neatly pinned in place. Surrounding them are small thematic decorative props: {argument name="Props" default="dried roses, vintage perfume bottles, silk ribbon"}. Elegant calligraphy on the matte paper backdrop reads: {argument name="Text" default="Midnight Elegance"}. Soft studio lighting accentuates the rich texture and drape of the fabric.

Bottom Section: Naked-Eye 3D Reality
The lower half creates a hyperrealistic "naked-eye 3D" illusion. A rectangular picture-frame border sits directly beneath the top box. A stunningly realistic young woman {argument name="Model Description" default="a poised East Asian model with long wavy black hair, subtle smoky eyes, and a confident ga
A highly structured JSON prompt for generating a cinematic, long-exposure urban fashion photo of a young woman in a subway station at 2 AM, emphasizing motion blur from a passing train, cold fluorescent lighting, and a detached, melancholic 'it-girl' aesthetic.
{
  "image_prompt": {
    "meta": {
      "aspect_ratio": "9:16",
      "style": "Long-exposure urban fashion, motion blur"
    },
    "subject": {
      "description": "22-year-old girl with a detached, melancholic 'it-girl' look",
      "face": "Perfectly still and sharp, staring blankly into the distance, pale skin, natural lips",
      "skin": "Glowing under cold fluorescent lights, contrast with the dark surroundings",
      "hair": "Long hair blowing slightly from the wind of a passing train",
      "pose": "Standing perfectly still on the yellow safety line of a subway platform, arms down, bag hanging loosely",
      "outfit": "Short pleated skirt, oversized vintage blazer, white socks with loafers, headphones around the neck"
    },
    "environment": {
      "location": "Empty, modern subway station at 2 AM",
      "background_elements": [
        "A passing train appearing as a streak of blurred white and red lights",
        "Symmetrical station pillars leading into a dark tunnel",
        "Clean, reflective floor with industrial textures"
      ]
    },
    "lighting": {
      "type": "Flickering overhead fluorescent + Motion-blurred train lights",
"characteristicA 30-second, 9:16 photoreal 3D animation of four costumed cats (witch, ghost, skeleton, pumpkin) and an upright Frankenstein tiger dancing in sync in a sunny Halloween village courtyard, scripted in six timed scenes with audio cues and strict character-consistency rules.
Video Style: Ultra-realistic 3D anthropomorphic animals, adorable Halloween costumes, energetic synchronized dancing, whimsical fantasy atmosphere, vibrant autumn colors, cinematic animation, realistic fur textures, smooth character movements, 9:16 vertical format, 4K quality.

SETTING:

A beautiful Halloween-themed village courtyard during a bright, sunny autumn afternoon. A magnificent Victorian haunted mansion stands in the background, decorated with glowing jack-o'-lanterns, carved pumpkins, hanging lanterns, cobwebs, spooky ornaments, and Halloween decorations. Tall maple trees with brilliant orange, golden-yellow, and crimson-red leaves surround the courtyard. Fallen autumn leaves cover the cobblestone pathway. A vivid blue sky with fluffy white clouds creates a cheerful Halloween atmosphere.

MAIN CHARACTERS:

Four adorable anthropomorphic cats and one large anthropomorphic tiger, all standing upright on their hind legs.

Witch Cat: A fluffy black-and-white cat wearing a pointed black witch hat, a purple witch dress, and a flowing purple cape.

Ghost Cat: An adorable fluffy white cat wearing a flowing white ghost costume with a cute ghost hood and tiny black bow tie.

Skeleton Cat: A fluffy black-and-white cat wearing a black skeleton jumpsuit featuring white bones and a small black Halloween hat.

Pumpkin Cat: A chubby orange tabby cat wearing a bright orange pumpkin costume with a carved jack-o'-lantern face and a small green pumpkin-stem hat.

Frankenstein Tiger: A large, realistic orange-and-black striped tiger standing upright like a human, wearing a green Frankenstein-style monster headpiece, a long dark-green Victorian coat, a purple waistcoat, and dark trousers.

All characters have realistic animal faces, expressive eyes, detailed fluffy fur, and adorable personalities.

SCENE 1 (0–5 seconds): GROUP DANCE INTRO

The camera opens with a wide cinematic shot of the Halloween courtyard.

Four adorable costumed cats stand in the foreground while the giant Frankenstein tiger stands behind them.

All characters begin dancing together to a playful, upbeat Halloween rhythm.

The cats bounce on their hind legs, swing their little paws, wiggle their bodies, and move their heads in perfect synchronization.

The Frankenstein tiger performs exaggerated, funny dance moves behind them.

The camera slowly pushes forward.

SCENE 2 (5–10 seconds): CUTE CAT CLOSE-UPS

A quick transition reveals the fluffy white ghost cat and the black skeleton cat dancing side by side.

Both cats face the camera, raise their front paws near their faces, and perform matching playful paw gestures.

Their costumes bounce naturally as they move.

The ghost cat tilts its head adorably while the skeleton cat gives a confident little pose.

Smooth camera tracking, realistic fur movement, cheerful expressions.

SCENE 3 (10–15 seconds): GROUP DANCE FROM BEHIND

The camera moves behind the dancing cats.

The witch cat's purple cape sways dramatically, the ghost cat's white costume flutters, and the skeleton cat wiggles its hips.

The cats perform synchronized side steps toward the Frankenstein tiger.

The tiger dances enthusiastically in front of the haunted mansion.

Autumn leaves scatter gently across the cobblestones.

SCENE 4 (15–20 seconds): FRANKENSTEIN TIGER SOLO

A medium close-up focuses on the giant Frankenstein tiger.

The tiger performs a hilarious solo dance, crossing its furry arms over its chest, swinging its shoulders, moving its paws rhythmically, and nodding its head.

Its long green coat sways naturally.

The tiger maintains a serious, comical facial expression while dancing.

The camera gently zooms closer, emphasizing the tiger's expressive face and detailed striped fur.

SCENE 5 (20–25 seconds): PUMPKIN CAT TAKES CENTER STAGE

The adorable chubby orange pumpkin cat steps into the center of the courtyard.

It performs a funny bouncing dance, swinging its tiny paws from side to side.

The pumpkin costume jiggles with every movement.

The other cats dance around it while the Frankenstein tiger follows the rhythm in the background.

A quick, playful camera movement emphasizes the energetic choreography.

SCENE 6 (25–30 seconds): FINAL HALLOWEEN DANCE

All five characters gather together for a final synchronized Halloween dance.

The cats perform matching paw waves, little jumps, shoulder movements, and playful head tilts.

The Frankenstein tiger stands behind them, performing exaggerated monster-style dance gestures.

The camera alternates between a wide group shot and a close-up of the tiger.

The video ends with the Frankenstein tiger crossing its furry arms confidently while the cats strike adorable Halloween poses.

CAMERA & VISUAL QUALITY:

Photorealistic 3D animal animation, realistic fluffy fur, expressive animal faces, physically accurate costume movement, cinematic daylight, vibrant autumn colors, natural shadows, detailed Victorian architecture, smooth tracking shots, playful close-ups, energetic choreography, adorable character expressions.

AUDIO:

Upbeat, playful Halloween dance music with a catchy rhythm, funny spooky sound effects, light monster growls, cheerful cat meows, and synchronized dance beats.

IMPORTANT INSTRUCTIONS:

Maintain identical character appearances, costume designs, fur patterns, and proportions throughout every scene. All animals must remain upright on two hind legs while dancing. Dance movements must be smooth, rhythmic, and synchronized. No character morphing, no extra limbs, no costume changes, no distorted faces, no flickering, no text overlays, no subtitles, and no watermarks.

A highly structured JSON prompt for generating a cinematic, long-exposure urban fashion photo of a young woman in a subway station at 2 AM, emphasizing motion blur from a passing train, cold fluorescent lighting, and a detached, melancholic 'it-girl' aesthetic.

This user is testing GPT-image 1.5 and notes that the results are quite good. The actual prompt used to generate the image is located in the ALT text (alternative text) of the attached image, which describes a detailed scene involving a girl, a futuristic city, and specific lighting and composition elements.
A girl with {argument name="hair color" default="long black hair"} and {argument name="clothing" default="a white dress"} stands on the rooftop of a skyscraper in a futuristic city, looking up at the night sky. The city is illuminated by neon lights and holographic advertisements. The composition is a wide shot, with the girl positioned slightly off-center to the right. The lighting is dramatic, with strong shadows and highlights emphasizing the contrast between the girl and the vibrant city lights. The style is cinematic and highly detailed, reminiscent of {argument name="art style" default="cyberpunk anime"}.
This is a system description for the Nano Banana Pro V1.8.91 [ZENITH UPGRADE], which allows for 'free input' to generate fully autonomous 4-panel manga. The AI handles concept generation, direction, and drawing based on the theme provided by the user, moving from autonomous generation to co-creation.
好きなテーマを投げるだけで、AIがネタ出し・演出・作画を完璧にこなします。

This is a system description for the Nano Banana Pro V1.8.91 [ZENITH UPGRADE], which allows for 'free input' to generate fully autonomous 4-panel manga. The AI handles concept generation, direction, and drawing based on the theme provided by the user, moving from autonomous generation to co-creation.

A simple prompt asking the AI to generate the scene that occurred five minutes prior to the image shown in the tweet, implying a narrative context is needed to explain why the subject is upset.

This prompt is used with ChatGPT Image to generate an image where every detail is aligned and every color tells a story, suggesting a highly detailed and aesthetically pleasing visual output.
A high-resolution, cinematic photograph of a lone, ancient lighthouse standing on a rugged cliff edge at sunset. The sky is dramatic, painted in deep oranges, purples, and blues, with rays of light breaking through the clouds. Waves crash violently against the rocks below, creating a fine mist. The lighthouse beam cuts sharply through the twilight air. The texture of the stone and the weathered metal of the lantern room are highly detailed. The overall mood is one of isolation, power, and enduring beauty. Shot on a large format camera, 85mm lens, f/2.8, golden hour lighting.

A simple prompt asking the AI to generate the scene that occurred five minutes prior to the image shown in the tweet, implying a narrative context is needed to explain why the subject is upset.
Show me 5 minutes earlier so I can see why he’s upset.

A simple prompt demonstrating how Nano Banana Pro can be used to generate specific views (like a side view) of a character initially created in Midjourney, requiring the original image as a reference.
Give me the right side view of this image

A simple prompt demonstrating how Nano Banana Pro can be used to generate specific views (like a side view) of a character initially created in Midjourney, requiring the original image as a reference.

A meta-prompt template for Nano Banana Pro designed to generate a multi-panel infographic grid for visual comparison. This specific example is set up to compare bare legs with various styles of stockings, ensuring absolute consistency in lighting, angle, and composition across all panels to isolate the variable being tested.
# Role: Comparison Infographic Generator (Design-Centric with Toggles)

# === USER INPUT SETTINGS (FILL THESE IN) ===
# 1. Grid Size (e.g., "2x2 (4 panels)", "3x3 (9 panels)"):
{argument name="宫格数量" default="1x5"}

# 2. Base Subject Description (Identical base scene for all panels):
[{argument name="主体描述" default="冷白纤细白皙的亚洲女性的腿部,皮肤细腻光滑,没有杂色,几乎看不到毛孔毛囊。皮肤不干燥,稍微湿润"}]

# 3. Variations Theme (What is being compared?):
{argument name="变量主题" default="裸腿与不同丝袜"}

# 4. Show Text Overlay at Bottom (Yes/No):
YES

# ===========================================

# Task Description:
Generate a multi-panel infographic grid chart for a comparative visual study based on the User Input Settings above. The goal is to showcase different textural or stylistic variations (defined in the data list below) applied to the identical Base Subject defined above.

# Global Constraints & Style:
1.  **Layout:** A **[Insert setting from "1. Grid Size" here]** infographic grid chart.
2.  **Consistency is Key:** The Base Subject, camera angle, composition, and lighting must remain absolutely identical across ALL panels to emphasize only the specific variations.
3.  **Photography Style:** Clean, controlled studio photo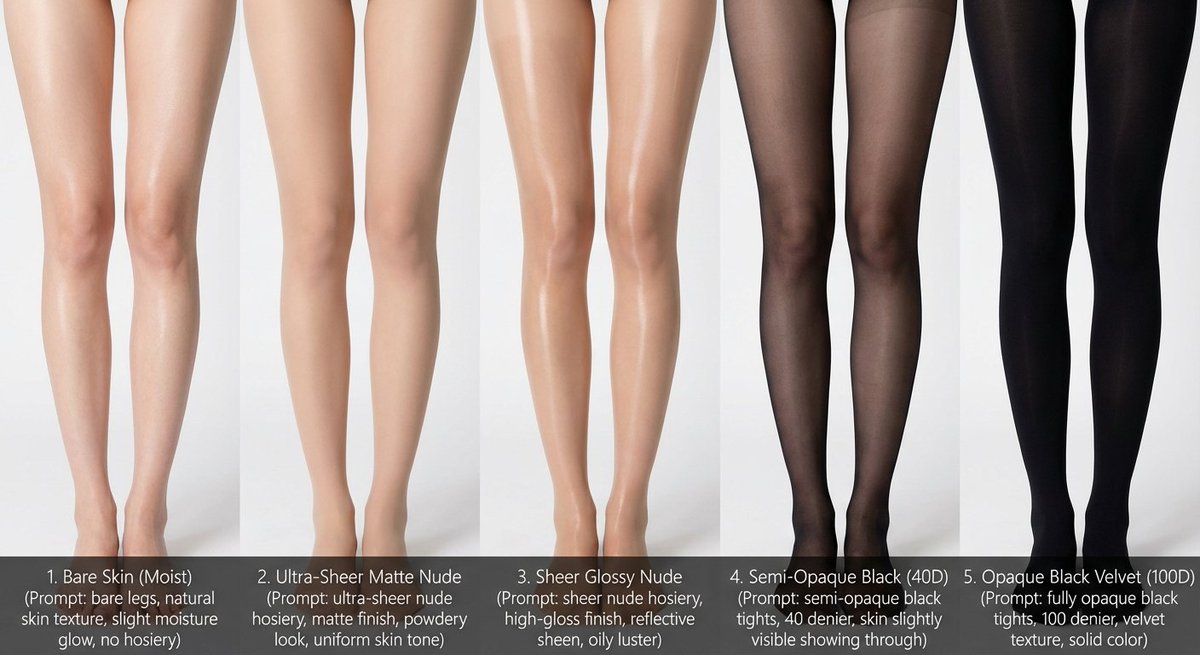
A meta-prompt template for Nano Banana Pro designed to generate a multi-panel infographic grid for visual comparison. This specific example is set up to compare bare legs with various styles of stockings, ensuring absolute consistency in lighting, angle, and composition across all panels to isolate the variable being tested.

A prompt for generating a high-fashion editorial image of a young man using an exaggerated fisheye lens close-up. The image features bold composition, a solid orange background, and Gen Z summer fashion, requiring the model to maintain facial features from a reference photo.
Create a A high-fashion editorial image of a young man, of the person from the uploaded character reference photo. KEEP FACE FEATURES AS ORIGINAL at all times. A high-fashion editorial image captured in an exaggerated fisheye lens close-up. The camera is angled slightly from below, and the man is crouching or squatting forward with both hands resting on his knees, leaning his upper body toward the lens. His face is looking downward into the camera, exaggerated by fisheye distortion so it appears large and rounded, with cartoonish proportions. He has a neutral smile, relaxed and completely smile, expression confident but emotionless.

He wears a trendy, summery knitted shirt in a pastel green shade light, breathable, with visible texture, reflecting Gen Z summer fashion. He also wears oversized black-framed sunglasses, with lenses tinted in light green.

The background is a clean, solid orange color with soft, realistic studio lighting, creating gentle shadows cast from his head, shoulders, and arms.

No direct sunlight light is controlled and evenly diffused, like a fashion set. The overall style is playful, surreal, and modern, inspired by 2025 Gen Z fashion culture and bold edito